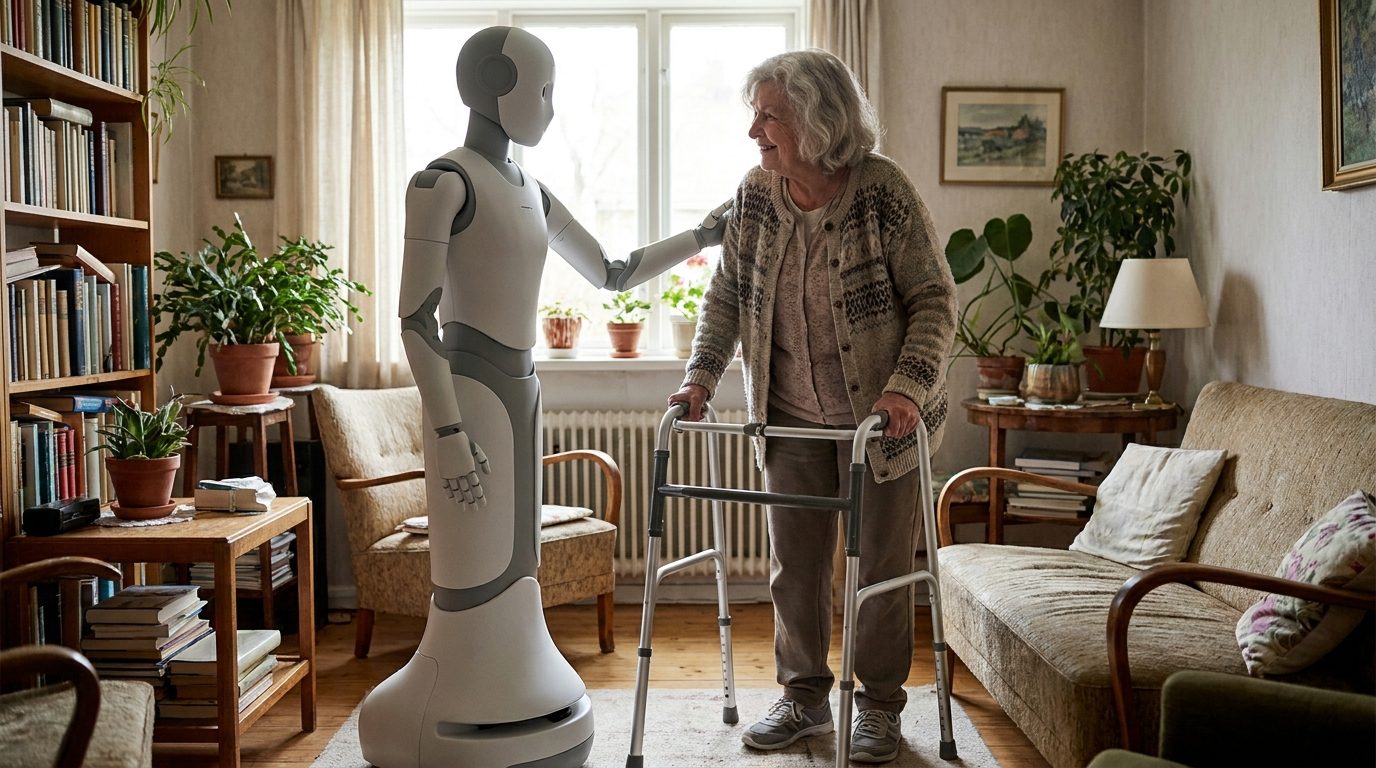
Robots, smart glasses and care apps are moving into patients' homes. Today the only test is a real patient.
HealthDojo turns clinical guidelines into synthetic homes with exact labels, so your team finds the edge cases and trains on them before a patient ever does.

About to share homes with older adults. They have to know a towel bar is not a grab bar.
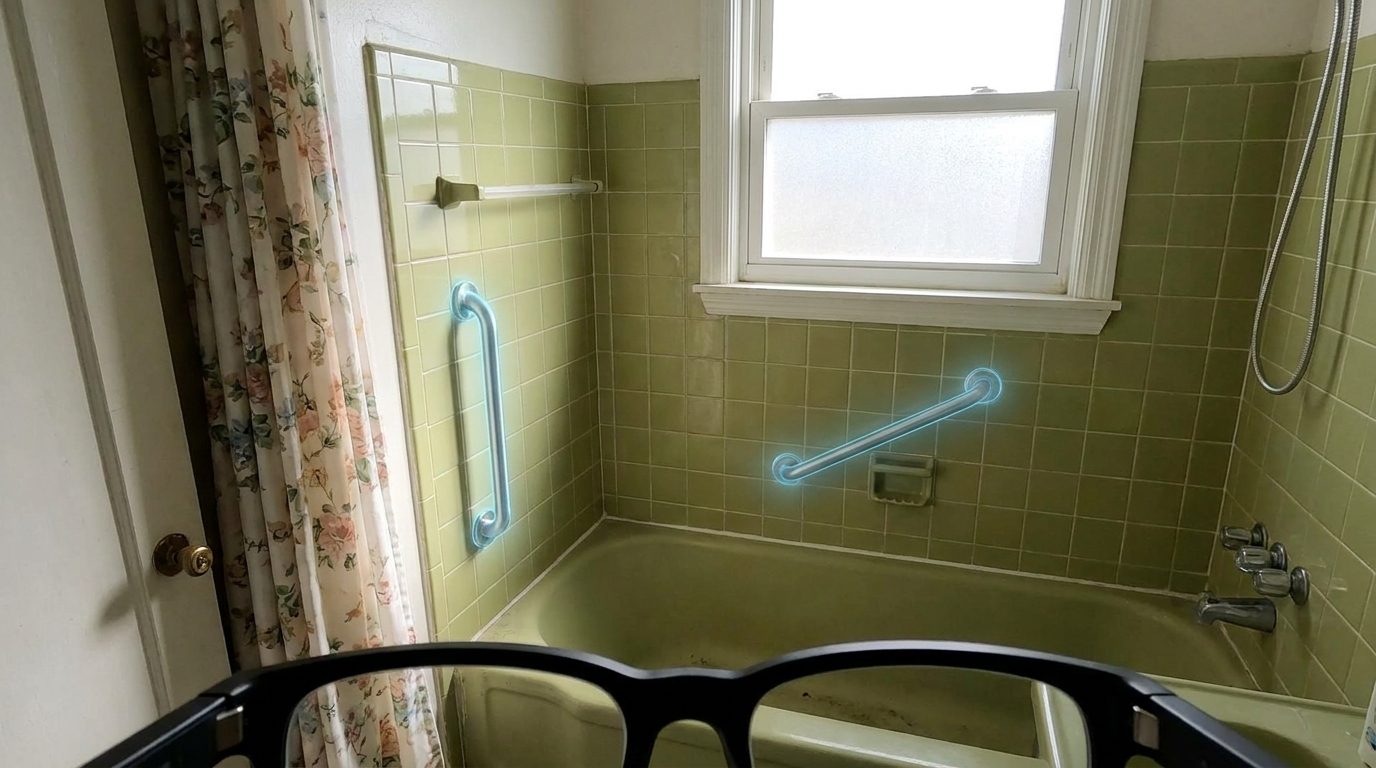
Seeing the home through the user's eyes, in every room the patient walks through.
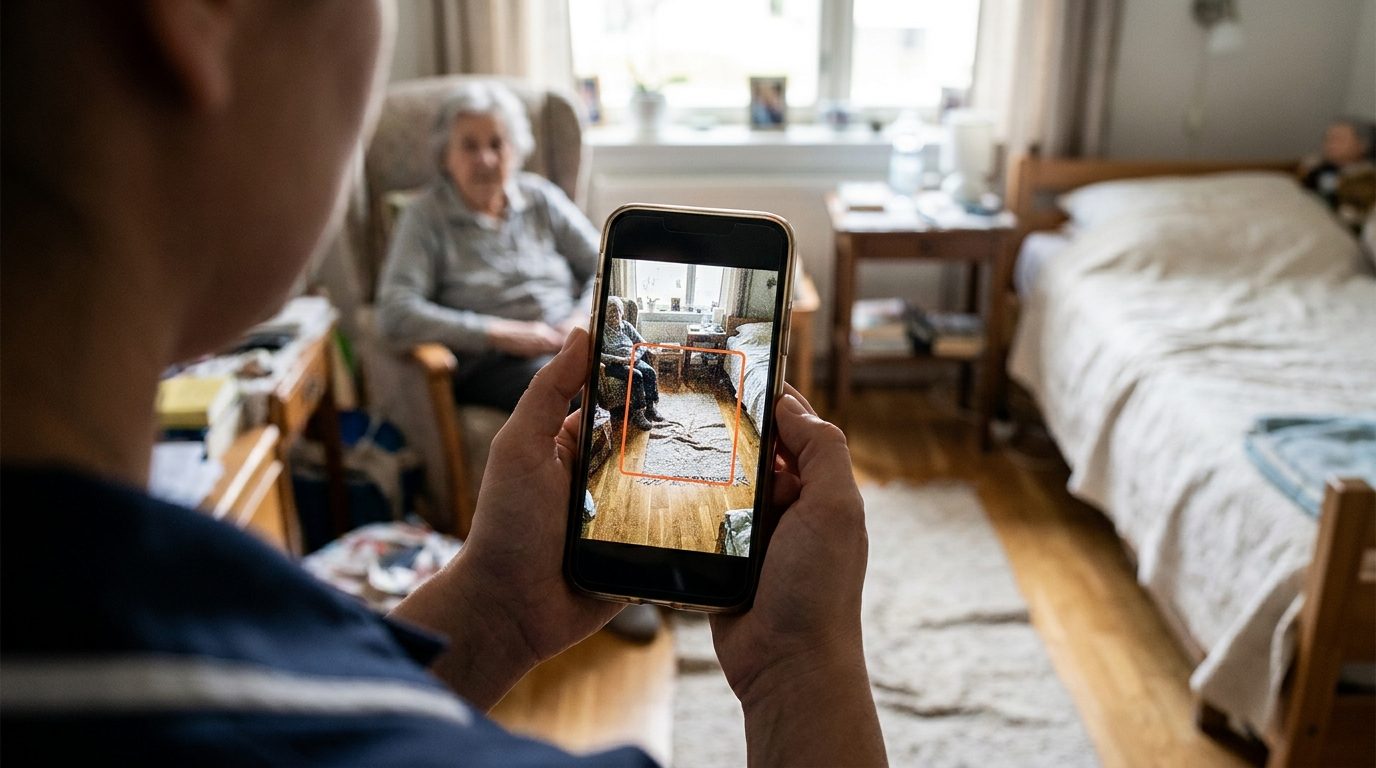
A wave of apps assessing homes from a phone camera, all judging safety from pixels.
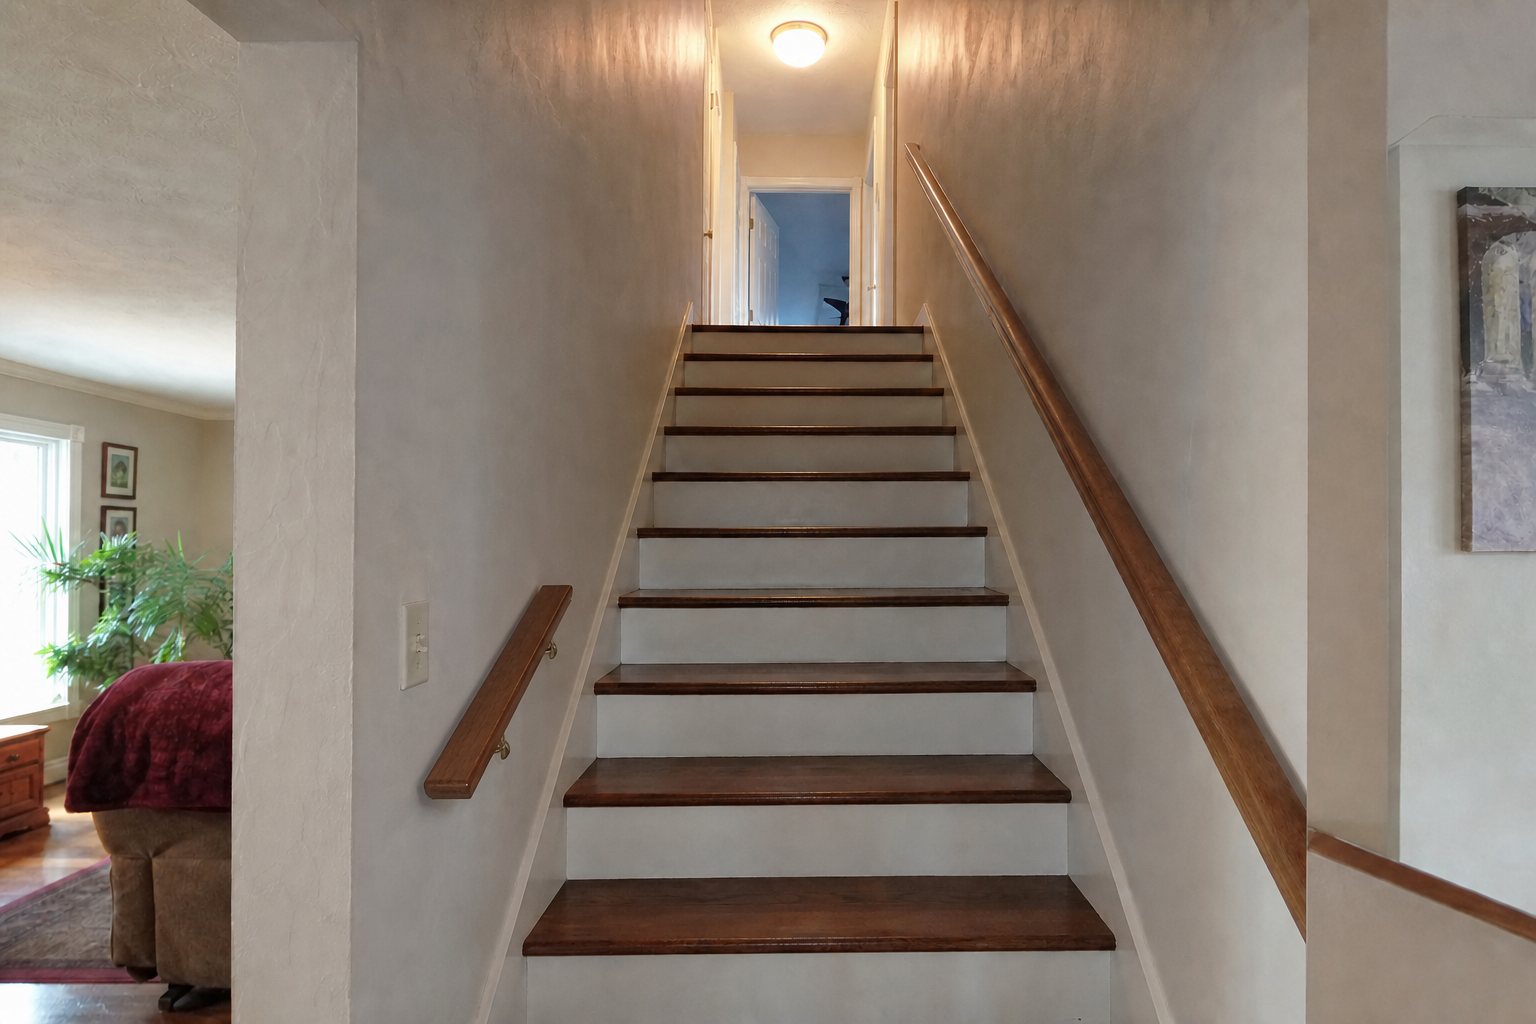
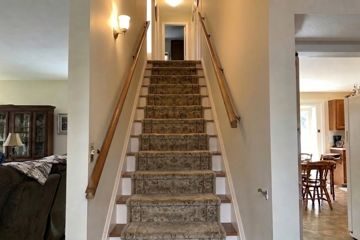
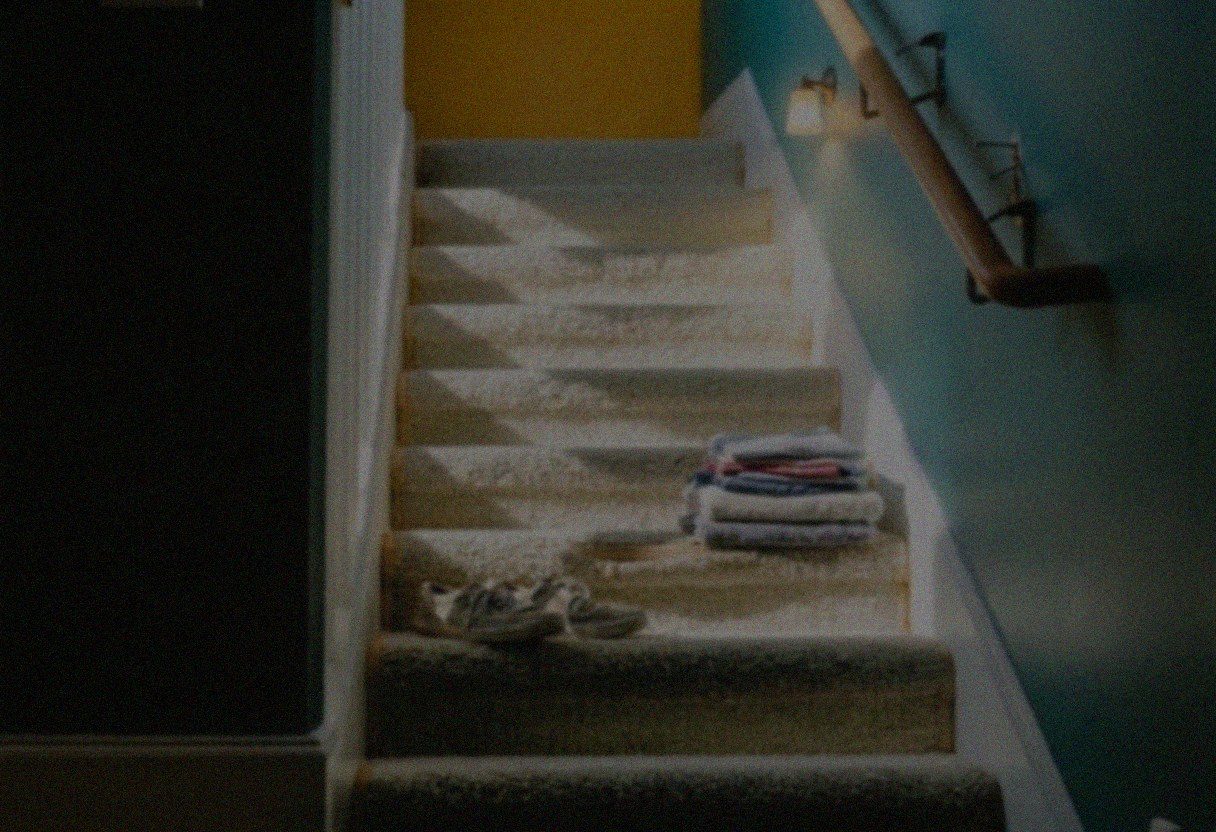
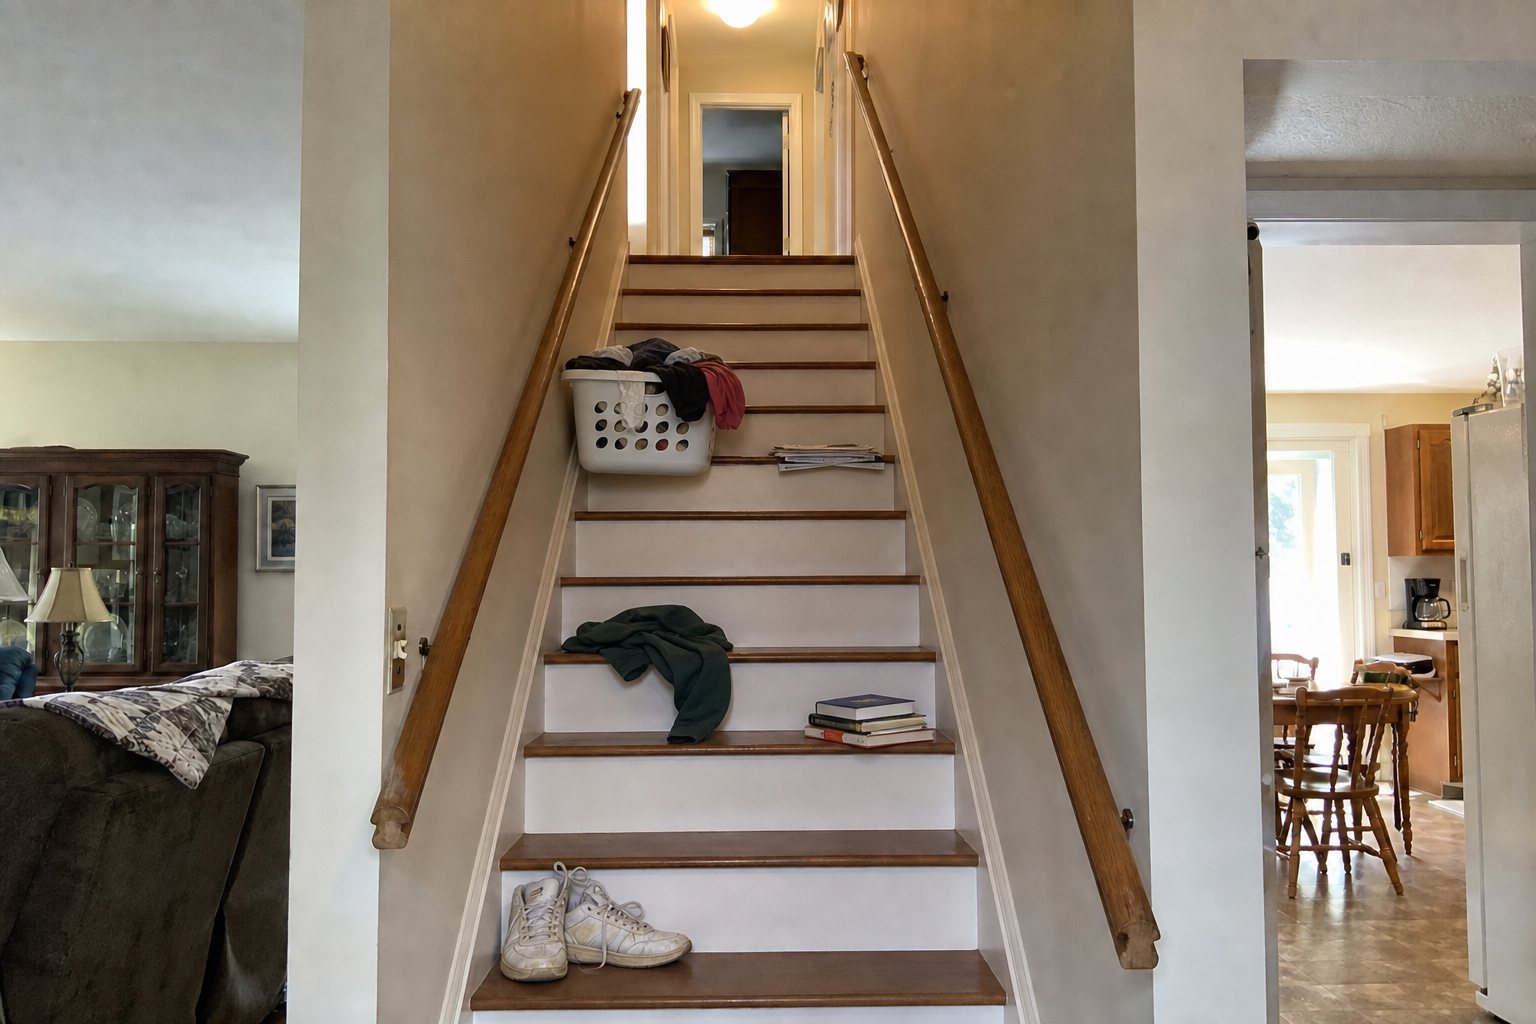
“Stairs and steps: keep objects off the stairs; fix loose or uneven steps; make sure carpet is firmly attached to every step, or remove it and put non-slip rubber treads on the stairs; handrails on both sides, as long as the stairs; fix loose handrails.”

Every image is built from the rubric: label first, then paint, then verify.

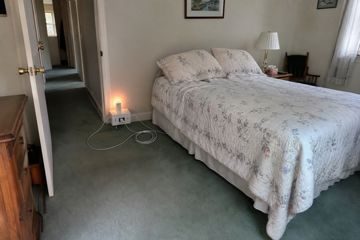
One clear hazard, clean room, good light.

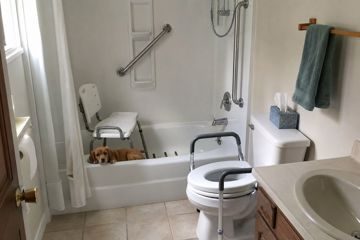
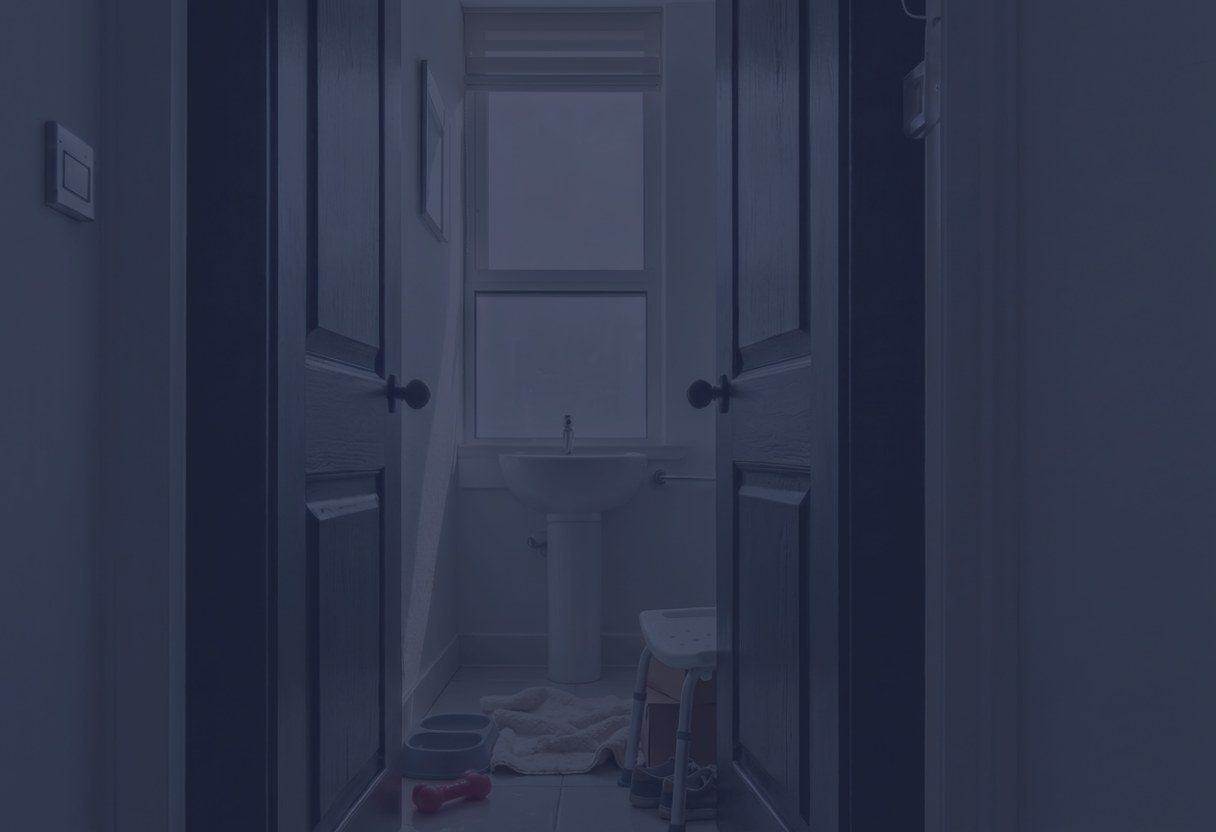
Judge adequacy: a towel bar, a short rail, a low-contrast mat.

Two hazards plus a safe look-alike that must not be flagged.

Three or four hazards in dim, noisy, unfamiliar rooms.

Safe-but-scary rooms next to dense hazard rooms, in poor light.

Check for Safety, compiled into labelled homes where a missing grab bar or a cluttered stair is the test.
Open the simulator →
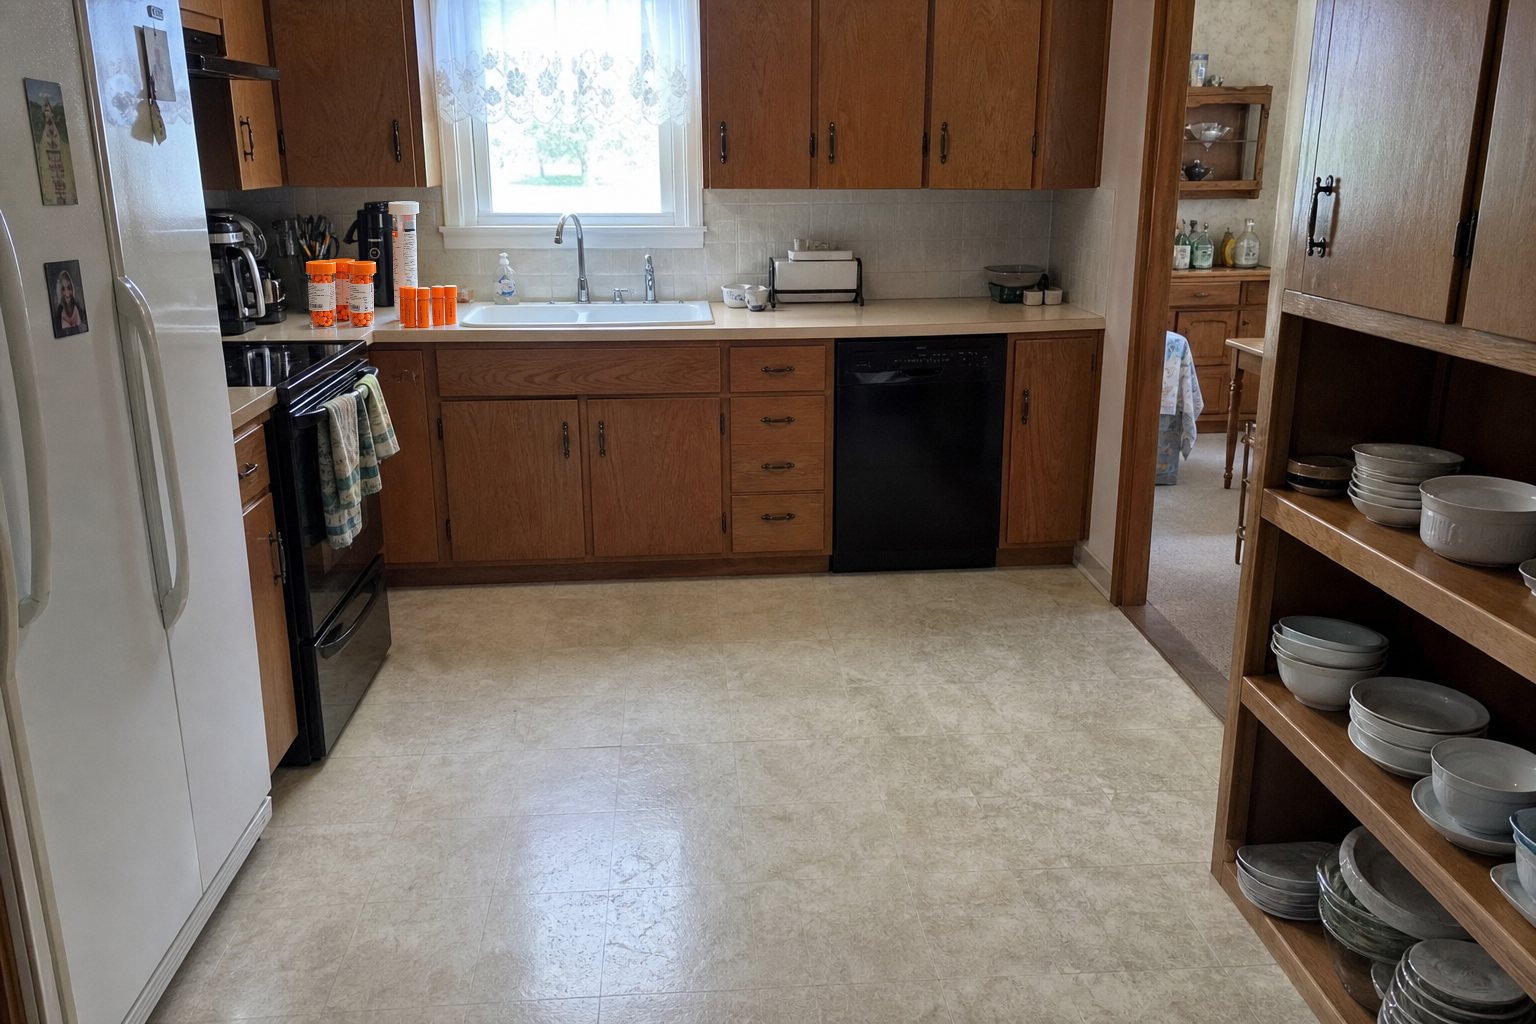
Wandering exits, medications left out and floors that read as holes, judged the way a caregiver would.
Open the simulator →| # | Model | Provider | Score | Recall | False alarms |
|---|---|---|---|---|---|
| 1 | Claude Opus 5.5 | Anthropic | 0.92 | 100% | 17% |
| 2 | GPT-5.6 Sol | OpenAI | 0.90 | 97% | 18% |
| 3 | GPT-5.6 Terra | OpenAI | 0.84 | 83% | 14% |
| 4 | Kimi K3 | Moonshot | 0.84 | 93% | 24% |
| 5 | Grok 4.6 | xAI | 0.81 | 73% | 11% |
| 6 | Claude Sonnet 5 | Anthropic | 0.81 | 87% | 26% |
| 7 | Llama 4 Maverick | Meta | 0.79 | 83% | 26% |
| 8 | Nova Pro | Amazon | 0.77 | 77% | 22% |
| 9 | Qwen3-VL | Alibaba | 0.75 | 84% | 34% |
| 10 | Nova 2 Lite | Amazon | 0.73 | 67% | 20% |
| 11 | Gemma 3 27B | 0.70 | 81% | 40% | |
| 12 | Claude Haiku 4.5 | Anthropic | 0.70 | 83% | 43% |
| 13 | Nemotron Nano VL | NVIDIA | 0.70 | 90% | 50% |
| 14 | Mistral Large 3 | Mistral | 0.62 | 84% | 59% |

Train hazard perception in walkable 3D homes before meeting a walker.

Score what the device notices, and what it misses, from the user's view.

Find blind spots on synthetic homes instead of real patients.
Stability AI13 of 14 models we tested run on Bedrock: Claude, OpenAI GPT-5.6 via Bedrock, Nova, Llama 4, Qwen3-VL, Mistral, Gemma, Kimi, Grok, Nemotron.
Sonnet 5 on Bedrock drafts cited rubric rows; the verifier checks every scene before it counts. Grading against labels is deterministic, no LLM grades the answers.

Clean rooms, then hazards painted in one label at a time.
Gaussian-splat homes with collision meshes, walkable in the browser.
Models choose where to look, then flag what they find.
Narrates each walkthrough step.
Static site on S3; code and benchmark open on GitHub.